Posted At: Sep 26, 2026 - 59 Views
Artificial intelligence has spent much of the last few years moving toward bigger models, larger datasets, longer context windows, and increasingly powerful computing infrastructure. The assumption has often been that more capability requires more compute. But as AI moves from experimentation into everyday business operations, another question is becoming just as important: does every AI task really need that much computing power?
For many applications, the answer may be no. A customer service chatbot does not always need to generate a completely open-ended response. A workflow assistant may only need to choose the next action from a defined set of possibilities. A recommendation system may need to evaluate a limited number of options rather than generate a long explanation. In these situations, AI systems can be designed around a much smaller decision space, reducing unnecessary computation while still delivering useful results.
This points toward an important shift in AI development: the next breakthrough may not always come from making models larger. It may come from making AI more efficient, more focused, and better matched to the task it is performing.
AI Has a Compute Problem
Bigger Models Are Not Always Necessary
Large language models have demonstrated how powerful generative AI can be, but their capabilities come with significant computational requirements. Every interaction can involve processing context, generating tokens, evaluating possibilities, and producing a response. At massive scale, even small inefficiencies can become expensive when multiplied across millions of interactions.
This becomes particularly relevant for businesses that want to embed AI into high-volume workflows. A company may have thousands or millions of customer interactions, internal requests, product queries, or automated decisions taking place every day. If every interaction relies on a large generative model producing long responses, the accumulated compute requirements can become substantial.
The challenge is not necessarily that large models are inefficient in every situation. Their broad capabilities are valuable when a task requires reasoning, creativity, complex language generation, or handling unpredictable inputs. The opportunity lies in recognizing that not every AI problem requires the full capability of a large general-purpose model.
The Cost of Every AI Interaction
AI costs are influenced by more than the price of a model. Computing resources, infrastructure, latency, energy consumption, and the number of tokens processed or generated all contribute to the economics of AI at scale.
For simple tasks, generating a lengthy response can represent unnecessary work. If a chatbot only needs to determine whether a customer wants to track an order, return a product, change an address, or speak with an employee, it may not need to generate an elaborate answer from scratch every time.
This creates an opportunity to rethink the architecture of AI applications around the actual complexity of the problem.
What If AI Didn't Need to Generate Everything?
From Generating Responses to Selecting Responses
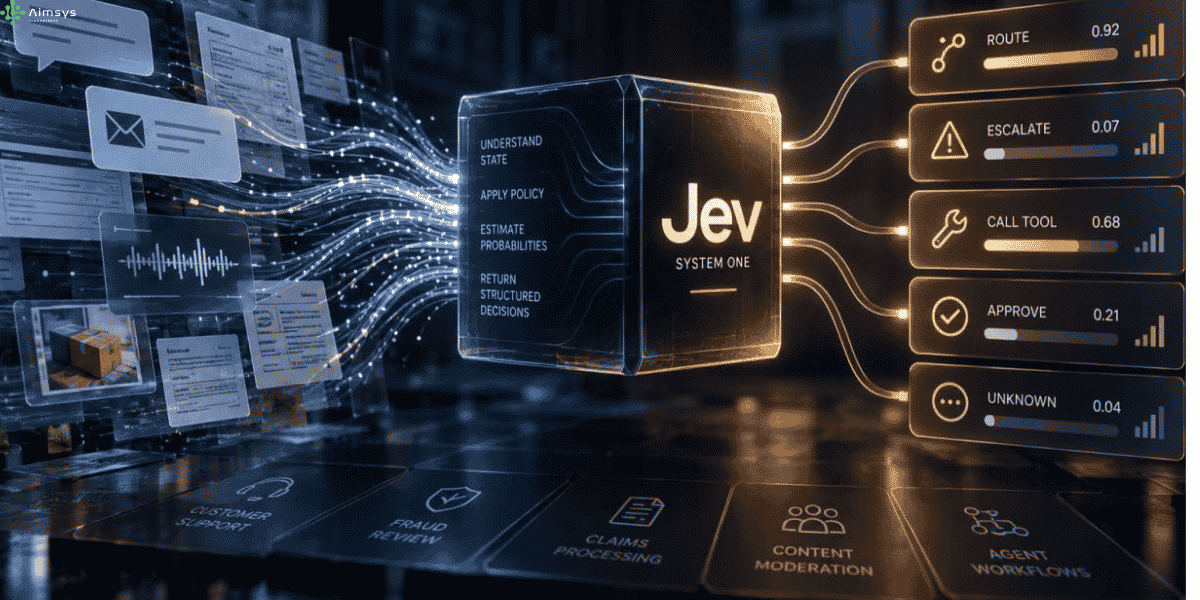
One way to reduce unnecessary computation is to narrow the number of possible outputs. Instead of asking an AI system to generate anything it wants, a system can provide a defined set of possible responses or actions and ask the model to determine which option best fits the situation.
Consider a customer service chatbot handling a common request. Instead of generating a completely new response for every interaction, the system could evaluate the customer's message and select from a set of approved responses. The AI's role becomes closer to decision-making than unrestricted text generation.
This can significantly reduce the amount of language the system needs to generate. Rather than producing a long response token by token, the system can identify the most appropriate predefined option and deliver it.
The customer still receives an AI-assisted experience, but the underlying computation can be much more focused.
Why Smaller Decision Spaces Matter
The number of possible outputs has a major impact on how much work an AI system needs to perform. A system dealing with thousands of possible responses has a different computational challenge from one choosing between ten clearly defined actions.
This does not mean that every AI application should use fixed responses. Instead, it suggests that organizations should examine where they can reduce unnecessary generation by designing more constrained decision environments.
For many enterprise workflows, the objective is not to produce the most creative answer possible. It is to make the correct decision quickly and consistently.
How Minimal AI Can Save Tokens
Reducing Unnecessary Generation
Tokens are a fundamental part of how many language-based AI systems process and generate information. When an AI system produces a long response, it generally requires more generation than a system that produces a short, focused output.
A minimal AI architecture can reduce this requirement by limiting what the system needs to generate. Instead of asking the model to write an entire response, it can ask the model to identify the appropriate response category, action, or predefined answer.
The final customer-facing response can then be delivered from an existing library of approved content.
This creates a simple but important distinction: AI does not always need to generate the final answer to make the final answer intelligent.
Fewer Tokens, Less Compute
Reducing unnecessary token generation can potentially reduce the amount of computation required for an interaction. At enterprise scale, even small reductions can become meaningful when applied across a large number of requests.
For organizations processing millions of AI interactions, token efficiency can influence infrastructure costs, response times, and overall system scalability. A smaller computational footprint can also make it easier to deploy AI in environments where resources are limited.
The objective is therefore not simply to use fewer tokens because fewer is always better. It is to avoid spending computational resources on work that does not contribute meaningful value to the outcome.
The Rise of Task-Specific AI
One Model Does Not Need to Do Everything
One of the biggest lessons emerging from enterprise AI adoption is that different problems require different levels of intelligence. A system that summarizes complex research may need broad language capabilities. A system routing customer requests may not.
Trying to use the same large model for every task can introduce unnecessary cost and complexity. Businesses can instead design AI systems around the specific requirements of each workflow.
A simple classification task might require a lightweight model. A customer support workflow could use AI to identify intent and then select an approved response. A recommendation engine could evaluate a defined set of products. More complicated tasks could still be routed to larger models when deeper reasoning or generation is necessary.
This creates a tiered AI architecture, where computational resources are matched to the complexity of the task.
Designing AI Around the Job
The starting point for enterprise AI should therefore be the business problem rather than the model.
Instead of asking, “How can we use the most powerful model available?” organizations can ask, “What is the minimum level of intelligence required to solve this problem reliably?”
That question can lead to very different technology choices.
For a simple workflow, a lightweight system may be sufficient. For a more complex problem, a larger model can be introduced. The result is an AI environment where compute is allocated according to business value rather than model popularity.
Lower Compute Could Mean Lower AI Costs
Reducing Inference Costs
AI inference—the process of running a model to produce an output—can become a major operational expense when AI applications reach high volumes. Every customer interaction, automated workflow, recommendation, and internal request can contribute to overall compute consumption.
Reducing the amount of computation required per interaction can therefore improve the economics of AI deployment. A system that uses a smaller amount of compute for routine tasks can potentially serve more users without requiring the same proportional increase in infrastructure capacity.
For enterprises, this could make AI more accessible across a broader range of workflows, including applications where the economics of using a large model for every interaction do not make sense.
Improving Speed and Latency
Lower compute can also have implications for speed. When an AI system has fewer computations to perform, it may be able to respond more quickly.
For customer-facing applications, latency can directly affect user experience. A customer asking a simple question about an order may not need a sophisticated reasoning process that takes several seconds. A focused AI system can potentially identify the relevant response much faster.
This becomes particularly valuable in high-volume environments where responsiveness matters.
Making AI More Energy Efficient
Compute efficiency also has an energy dimension. AI infrastructure requires electricity, and the growth of AI workloads is increasing demand for data center capacity.
Using smaller or more focused AI systems for appropriate workloads can potentially reduce the energy required for those interactions. This does not eliminate the environmental cost of AI, but it introduces another dimension of efficiency: doing the same useful work with less computation.
Minimal AI Doesn't Mean Less Intelligent
Intelligence Through Better System Design
There is an important misconception that a smaller or more constrained AI system must automatically be less intelligent. Intelligence is relative to the task being performed.
A system that needs to determine whether a customer wants to cancel an order does not need the same capabilities as a system writing a technical research paper. Using a large model for both tasks may provide unnecessary capability for the simpler problem.
A well-designed minimal AI system can therefore be highly effective within its intended environment. Its strength comes from focusing computational resources on the decisions that actually matter.
Accuracy Within a Defined Context
Constrained systems can also provide greater consistency when operating within clearly defined boundaries. If the possible responses are known in advance, organizations can review, test, and optimize those responses before deployment.
This can be particularly valuable in enterprise environments where reliability, compliance, and predictable behavior are important. Instead of allowing the system to generate unlimited possibilities, organizations can create controlled pathways for specific tasks.
The result can be an AI experience that is narrower in scope but more predictable and efficient.
Where Low-Compute AI Could Create Value
Customer Service
Customer service is one of the clearest examples of where minimal AI can be useful. Many customer requests are repetitive and fall into recognizable categories, such as order tracking, password assistance, appointment changes, refunds, or account questions.
An AI system can identify the customer's intent and route the request to the appropriate response or workflow. There is no need to generate an entirely new explanation when an approved answer already exists.
Enterprise Workflows
Businesses also have many internal processes that involve predictable decisions. AI can help classify requests, route documents, identify workflow stages, assign tasks, or select appropriate actions.
These systems can operate with smaller decision spaces while still providing meaningful automation.
Recommendations and Decision Support
Recommendation systems can also benefit from efficient AI architectures. Instead of generating unlimited possibilities, AI can evaluate a defined set of products, services, or actions and identify the most relevant option.
This can be particularly useful when the business already has structured data and clearly defined decision criteria.
High-Volume AI Applications
The value of low-compute AI becomes even more significant when the number of interactions is extremely high. A small efficiency improvement applied to millions of daily requests can create a substantial difference in infrastructure requirements.
This is where token efficiency can become a strategic advantage rather than simply a technical optimization.
The Future of Enterprise AI May Be Right-Sized
The next stage of enterprise AI may involve moving away from the idea that every problem requires the most powerful model available. Instead, organizations could build AI systems that combine different models, rules, retrieval systems, and decision mechanisms based on the needs of individual workflows.
A complex request could be escalated to a larger reasoning model, while a routine request could be handled by a lightweight system. Some workflows may require generative AI, while others may work better with classification or predefined responses.
This approach can create a more balanced AI architecture in which computational resources are used where they generate the most value.
Why Token Efficiency Could Become a Competitive Advantage
As AI adoption expands, businesses will increasingly need to consider the economics of running AI at scale. Model quality will remain important, but efficiency could become equally significant.
Two organizations may use AI for similar workflows, but the organization that can deliver the same outcome with fewer tokens, less compute, lower latency, and lower infrastructure costs may have a different cost structure.
This makes token efficiency more than an engineering concern. It can become part of an organization's broader AI strategy.
The competitive advantage may not come from simply having access to the largest model. It may come from knowing when not to use it.
Conclusion: The Next AI Breakthrough May Be Doing More With Less
The AI industry has spent years pushing toward larger models and greater computational power. That progress has produced remarkable capabilities, but the next phase of AI may require a different kind of innovation.
Instead of asking how much compute can be added to an AI system, organizations may increasingly ask how much compute is actually necessary.
For simple, high-volume tasks, minimal AI systems can potentially reduce token generation by narrowing the decision space, selecting from predefined responses, or routing requests through focused workflows. This can help reduce unnecessary computation while improving efficiency, speed, and scalability.
The goal is not to replace powerful AI models. Large models will continue to play an important role where complex reasoning, creativity, and open-ended generation are required. The opportunity is to use those capabilities selectively rather than automatically applying them to every problem.
The real AI breakthrough may not be making AI bigger. It may be making AI smarter about how much compute it actually needs.